Aggregators
|
|
|

Aggregators are special type of nodes that includes a generic CPT for any numbers of parents.
pyAgrum proposes a list of such aggregators. Some of then are used below.
In [1]:
import pyagrum as gum
import pyagrum.lib.notebook as gnb
In [2]:
min_x = 0
max_x = 15

bn = gum.BayesNet()
l = [bn.add(gum.RangeVariable(item, item, min_x, max_x)) for item in ["a", "b", "c", "d", "e", "f"]]

gum.config["notebook", "histogram_line_threshold"] = 15
In [3]:
nmax = bn.addMAX(gum.RangeVariable("MAX", "MAX", min_x, max_x))
bn.addArc(l[0], nmax)
bn.addArc(l[1], nmax)
bn.addArc(l[2], nmax)
In [4]:
nmin = bn.addMIN(gum.RangeVariable("MIN", "MIN", min_x, max_x))
bn.addArc(l[3], nmin)
bn.addArc(l[4], nmin)
bn.addArc(l[5], nmin)
In [5]:
nampl = bn.addAMPLITUDE(gum.RangeVariable("DELTA", "DELTA", 0, max_x - min_x))
bn.addArc(nmax, nampl)
bn.addArc(nmin, nampl)
In [6]:
nmedian = bn.addMEDIAN(gum.RangeVariable("MEDIAN", "MEDIAN", min_x, max_x))
for n in [l[0], l[1], l[2], l[3]]:
  bn.addArc(n, nmedian)
# potential for median has a size : 16^5=2^20 double !
In [7]:
nexists = bn.addEXISTS(gum.LabelizedVariable("EXISTS_0", "EXISTS"), 0)
bn.addArc(l[0], nexists)
bn.addArc(l[1], nexists)
bn.addArc(l[2], nexists)
In [8]:
nforall = bn.addFORALL(gum.LabelizedVariable("FORALL_1", "FORALL"), 1)
bn.addArc(l[3], nforall)
bn.addArc(l[4], nforall)
bn.addArc(l[5], nforall)
In [9]:
ncount = bn.addCOUNT(gum.RangeVariable("COUNT_1", "COUNT_1,", 0, 3), 1)
bn.addArc(l[0], ncount)
bn.addArc(l[1], ncount)
bn.addArc(l[2], ncount)
In [10]:
for nod in l:
  bn.cpt(nod).fillWith(1).normalize()
In [11]:
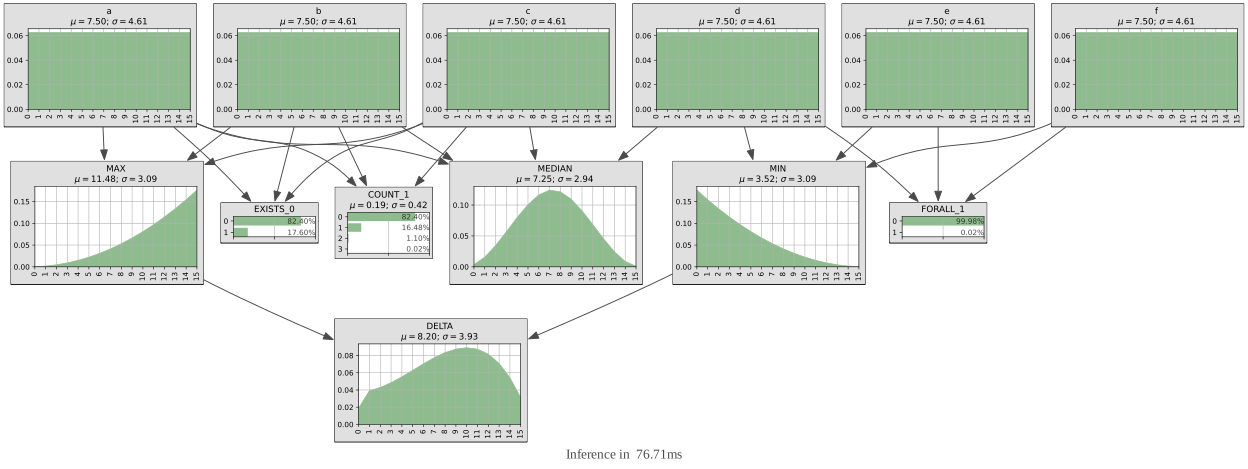
gnb.showInference(bn, size="13")
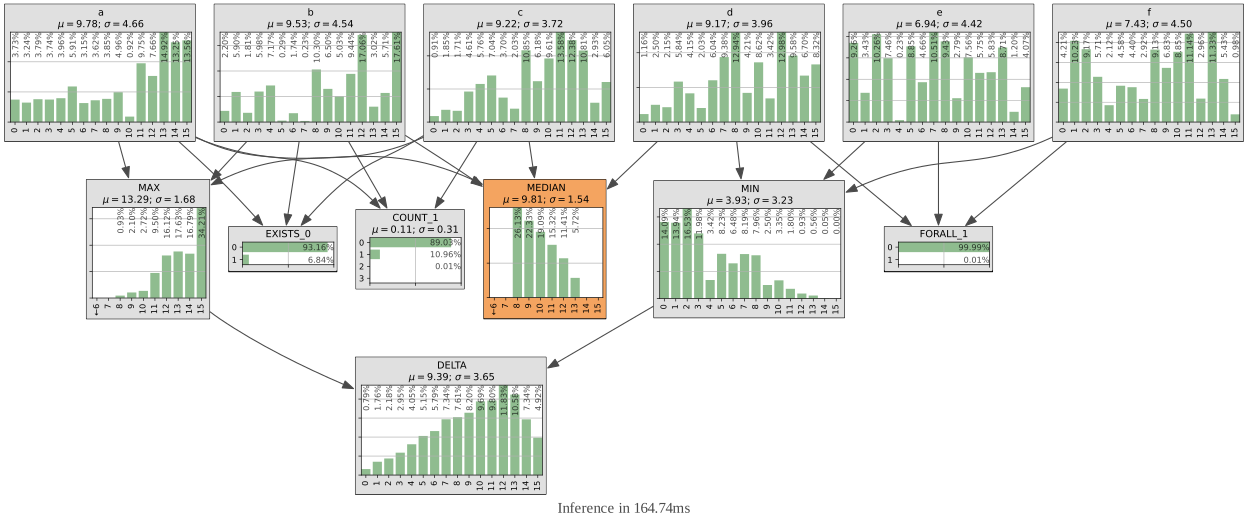
In [12]:
# dot | neato | fdp | sfdp | twopi | circo | osage | patchwork
gum.config["notebook", "graphRankDir"] = "LR"
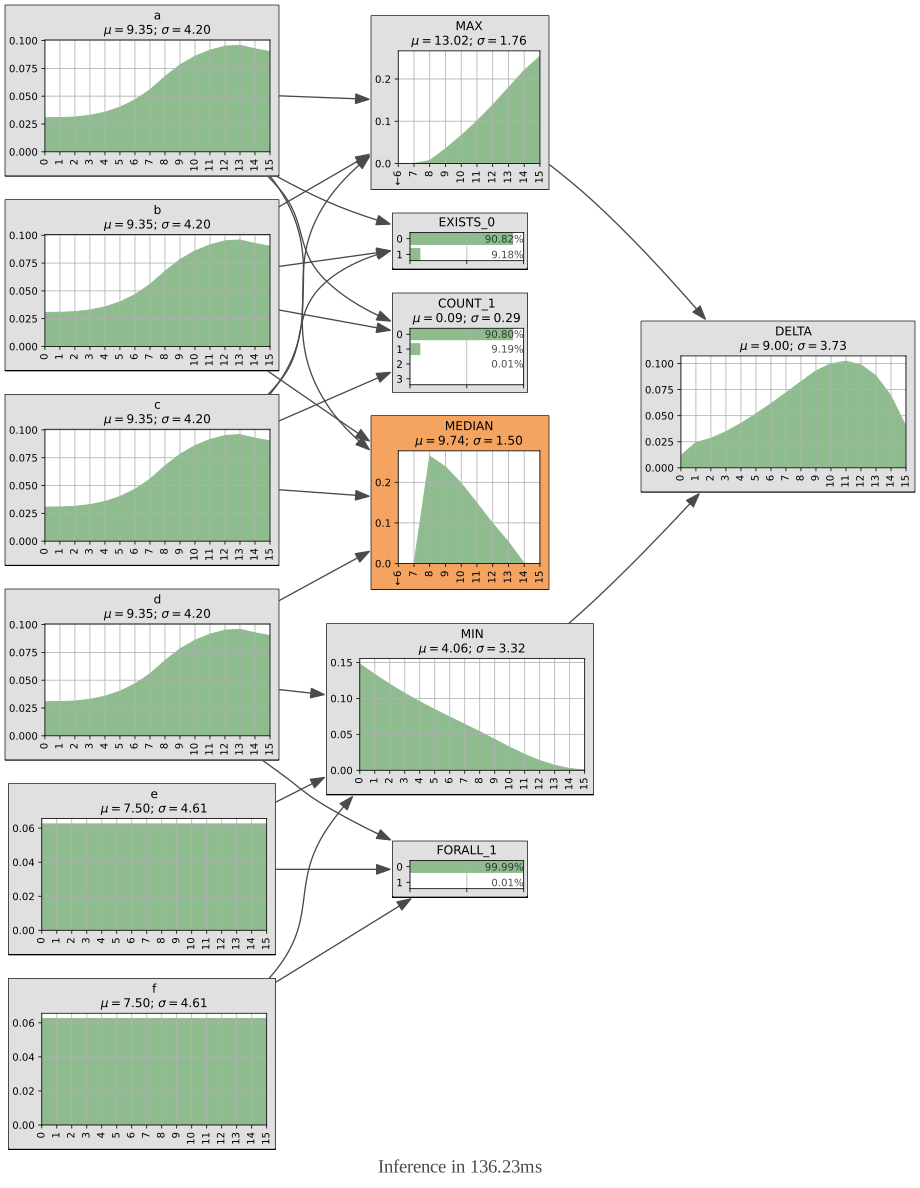
gnb.showInference(bn, size="13", evs={"MEDIAN": [0, 0, 0, 0, 0, 0, 0, 0, 1, 1, 1, 1, 1, 1, 0, 0]})
gum.config.reset()
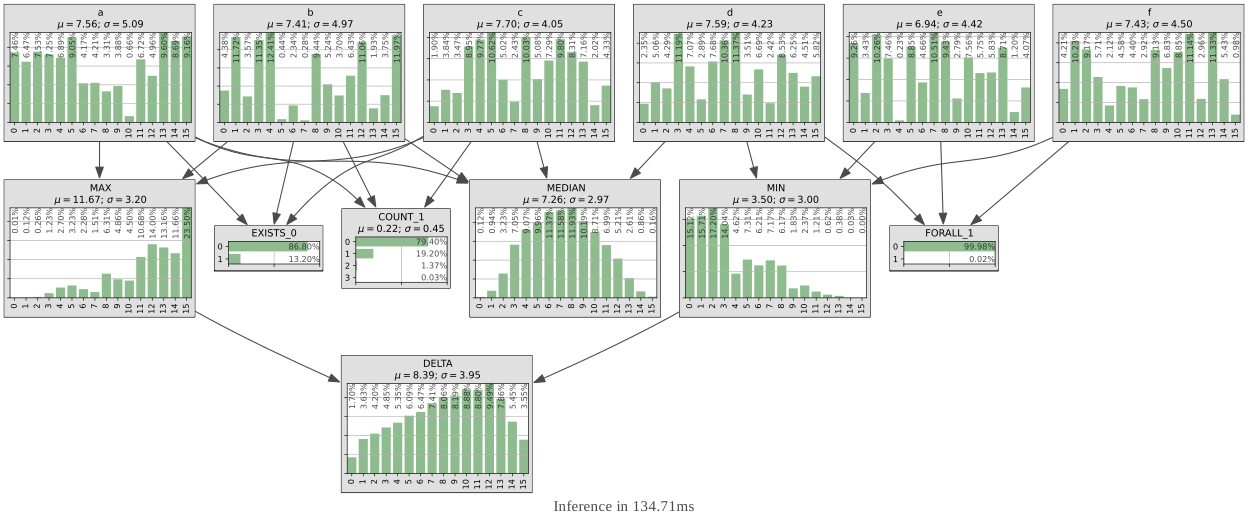
In [13]:
# if the roots do not have uniform but random distribution
for nod in l:
  bn.generateCPT(nod)

gnb.showInference(bn, size="13")
In [14]:
gnb.showInference(bn, size="13", evs={"MEDIAN": [0, 0, 0, 0, 0, 0, 0, 0, 1, 1, 1, 1, 1, 1, 0, 0]})
Input/Output
Aggregator (and ICI model) nodes have no stored CPT — the probability is computed on the fly from the aggregator’s rule. Saving to most BN file formats (BIF, BIFXML, DSL, XDSL, net, UAI, O3PRM) flattens that computed table into a full dense CPT before writing it out. Round-tripping through one of these formats therefore loses the aggregator: reloading the file gives back a plain node with a dense CPT, not an aggregator (bad round trip).
Only aGrUM’s native jgum (JSON) and bgum (binary) formats preserve the aggregator/ICI type exactly. Instead of a flat array of probabilities, the cpt entry for such a node is a small object describing its type and parameters, e.g. {"kind": "aggregator", "name": "forall", "value": 1} for a FORALL node, or {"kind": "ici", "name": "MultiDimNoisyORCompound", ...} for a Noisy-Or node.
In [15]:
import json
import os
import tempfile

demo = gum.BayesNet()
ps = [demo.add(gum.RangeVariable(f"P{i}", "", 0, 9)) for i in range(4)]
for i in range(4):
  demo.cpt(f"P{i}").randomCPT()
nsum = demo.addSUM(gum.RangeVariable("SUM", "", 0, 9))
for p in ps:
  demo.addArc(p, nsum)

with tempfile.TemporaryDirectory() as d:
  bif_path = os.path.join(d, "demo.bif")
  jgum_path = os.path.join(d, "demo.jgum")
  gum.saveBN(demo, bif_path)
  gum.saveBN(demo, jgum_path)
  bif_size = os.path.getsize(bif_path)
  jgum_size = os.path.getsize(jgum_path)
  with open(jgum_path) as f:
    jgum_content = json.load(f)

print(f"BIF  (dense CPT)         : {bif_size:>8} bytes")
print(f"jgum (compact aggregator): {jgum_size:>8} bytes")
print()
print(json.dumps(jgum_content, indent=2))
BIF  (dense CPT)         :   371373 bytes
jgum (compact aggregator):     1171 bytes

{
  "type": "BN",
  "GumJsonVersion": "1.0",
  "nodes": [
    "P0[10]",
    "P1[10]",
    "P2[10]",
    "P3[10]",
    "SUM[10]"
  ],
  "parents": {
    "P0": [],
    "P1": [],
    "P2": [],
    "P3": [],
    "SUM": [
      "P0",
      "P1",
      "P2",
      "P3"
    ]
  },
  "cpt": {
    "P0": [
      0.18860514283555507,
      0.0795090292393466,
      0.020416855453333993,
      0.03824350588919484,
      0.10504745814658306,
      0.13111658958670946,
      0.011326512221508489,
      0.1377975616708077,
      0.21103906303722142,
      0.07689828191973935
    ],
    "P1": [
      0.0634957352555945,
      0.049148045246097366,
      0.0648705243881559,
      0.13495263788361228,
      0.13544355103284328,
      0.024622995538563452,
      0.06009240981563374,
      0.40306461751096145,
      0.04291746971526189,
      0.02139201361327614
    ],
    "P2": [
      0.0562652009896491,
      0.051640950333211116,
      0.007616007881978304,
      0.012680539793720191,
      0.032331619720787935,
      0.44143930456154923,
      0.15759123264612973,
      0.052057473159765943,
      0.14884118695244586,
      0.03953648396076259
    ],
    "P3": [
      0.050064576685309635,
      0.0018560979311595463,
      0.026516337081772937,
      0.025556104662755375,
      0.06994705218599719,
      0.04069927574527202,
      0.04736686381954994,
      0.1319645815342686,
      0.38038672717846306,
      0.2256423831754517
    ],
    "SUM": {
      "kind": "aggregator",
      "name": "sum"
    }
  },
  "properties": {
    "software": "aGrUM 3.3.2",
    "creation": "2026-10-27 14:22:35.314",
    "lastModification": "2026-10-27 14:22:35.327"
  }
}
Indeed, the cpt for the node SUM should have a size of \(10^4=10000\) floats. Instead :
In [16]:
print(json.dumps(jgum_content["cpt"]["SUM"], indent=2))
{
  "kind": "aggregator",
  "name": "sum"
}
In [ ]: